Flash Attention
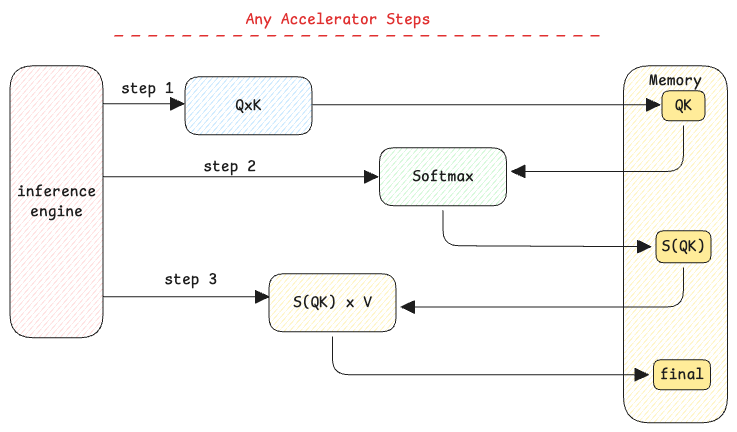
In a normal attention mechanism, the attention, softmax and matrix multiplication are calculated as separate steps. The inference engine calls different GPU kernel operations at each step.
Normal attention needs memory bandwidth
During normal attention, the intermediate results are stored in GPU memory. This needs to be read and written multiple times during the attention calculation.
Flash attention reduces the memory traffic.
it's a kernel feature
Flash attention is mostly a GPU kernel feature. The kernel implements flash attention.
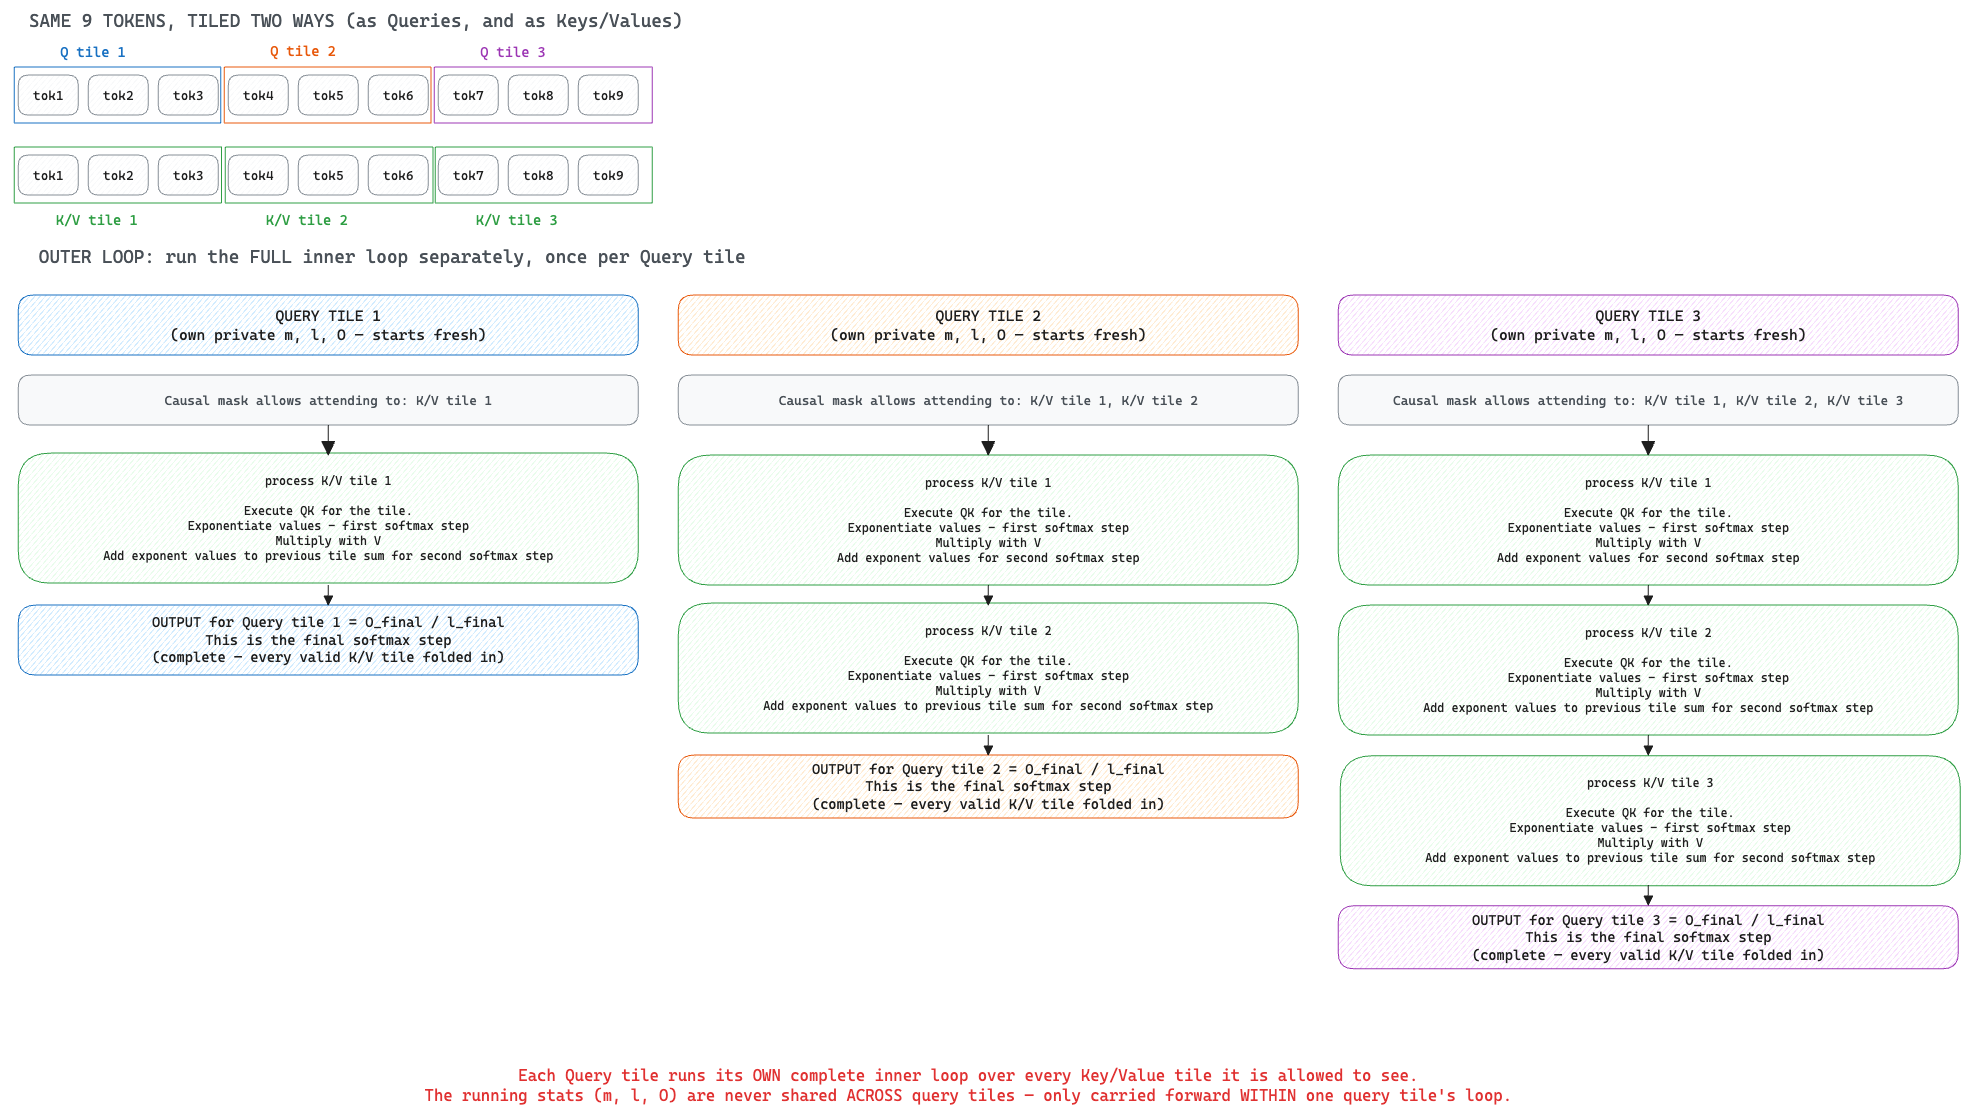
Flash attention solves this problem. In flash attention, the entire matrix is split into smaller tiles. Each tile is worked on independently.
How softmax works in flash attention?
The softmax calculation has two steps. See softmax details here. These two steps are done at different stages in flash attention
- Perform KV multiplication for each K and V tiles that has causal impact on the Q tile.
- Calculate the exponentiation for scores in KV output - softmax step 1.
- Calculate the sum of exponentiation values for each tile - softmax step 2a.
- Already perform V multiplication on the exponentiation values.
- At the end add all the values produced by step 3.
- Perform division of the scores with the final sum of scores - softmax step 2b.